Text Layer PDF Software: Make Scanned PDFs Searchable
A scanned PDF can look correct while containing only page images. A text-layer workflow runs OCR over those images and stores recognized text with the page so readers can search and select content without rebuilding the document from scratch.
Quick answer
Use a text-layer PDF when the original page appearance should remain visible but its words need to become searchable. Start from a clean, correctly rotated scan, choose the appropriate recognition language, save to a new output file, and verify names, dates, totals, page order, and search results before archiving or sharing it.
Understand What a PDF Text Layer Does
| PDF type | What the reader sees | What the reader can do |
|---|---|---|
| Image-only scan | A photograph of each page | View and print; text search usually fails |
| Searchable text-layer PDF | The original scanned page | Search, select, copy, and index recognized text |
| Editable conversion | Reconstructed text and layout | Edit more freely, with a greater chance of layout changes |
| Born-digital PDF | Text and graphics created by software | Usually searchable without OCR |
A hidden or aligned OCR layer does not prove that every character is correct. The scan remains the visual source of truth, while recognized text supports retrieval and reuse.
Prepare Scanned Pages for Better OCR
- Keep an untouched source copy.
Write the searchable result to a new file instead of replacing the only scan.
- Correct page orientation.
Rotate sideways or upside-down pages and deskew visibly tilted text.
- Use readable source quality.
Small characters, heavy JPEG artifacts, shadows, folds, and low contrast reduce recognition quality.
- Choose the correct language.
Mixed languages, unusual scripts, and specialist symbols require extra verification.
- Remove irrelevant borders carefully.
Preserve stamps, signatures, page numbers, and marginal notes that matter to the record.
Create a Text-Layer PDF with GiliSoft Formathor
Open Formathor and choose Text-layer PDF. Add the image-based PDF, confirm the intended pages and output folder, then run recognition on a representative document before processing a larger archive.
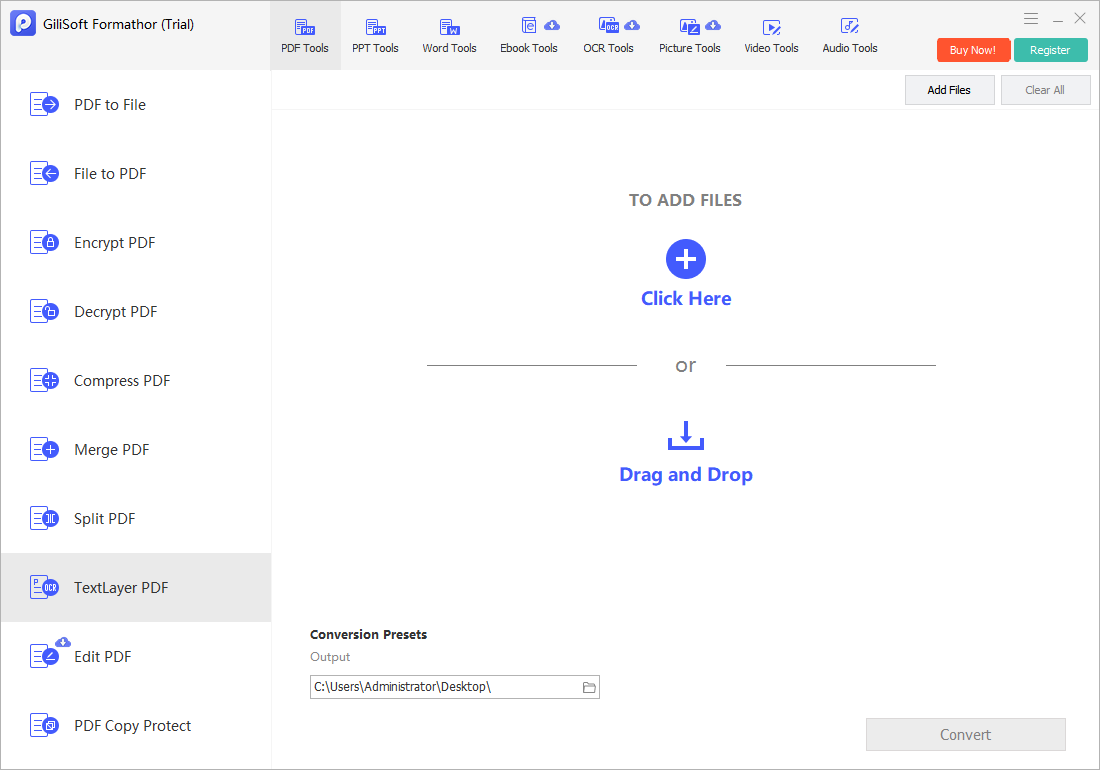
- Add the scanned PDF.
Confirm that it is image-based and that all pages open correctly.
- Select the recognition settings.
Choose the language and page range supported by the workflow.
- Choose a separate output folder.
Preserve the original scan and use a clear searchable filename.
- Run a small test first.
Use pages containing body text, numbers, columns, and stamps representative of the full file.
- Create and open the result.
Review it in the PDF reader used by the intended recipient or archive.
Verify Searchability and Recognition Accuracy
- Search for a phrase visible on the page.
Try a normal word and a name or number that matters to retrieval.
- Select text across multiple lines.
Check whether selection order follows the document's reading flow.
- Copy a sample into plain text.
Compare punctuation, spaces, accented characters, and line breaks.
- Check critical fields manually.
Proofread names, account numbers, dates, totals, legal clauses, and table values against the image.
- Inspect every representative page type.
Headers, footers, columns, rotated pages, handwriting, and faint originals can behave differently.
Choose Text Layer or Editable Conversion
Choose a text-layer PDF for archives, scanned contracts, invoices, manuals, and records whose original visual appearance must remain. Choose PDF-to-Word or another editable output when substantial rewriting is required, then expect to repair layout, fonts, tables, and reading order.
Text Layer PDF Software FAQ
What is a text layer in a PDF?
It is machine-readable text stored with a PDF page, often aligned behind or with a scanned page image. It enables search, selection, copying, and indexing while the scan remains visible.
Will adding a text layer change how the PDF looks?
A searchable text-layer workflow is intended to preserve the visible scan, but the finished file should still be compared with the source for page order, rotation, image quality, and unexpected rendering changes.
Can every scanned PDF become searchable?
Many clear printed scans can, but accuracy varies with resolution, contrast, language, layout, handwriting, damage, skew, and compression. Protected or damaged PDFs may need another authorized preparation step.
Is searchable PDF text fully accurate?
No OCR result should be assumed perfect. Proofread names, numbers, dates, totals, tables, and any text used for legal, financial, medical, or compliance decisions.
Should I replace the original scanned PDF?
Keep the original and save the searchable version separately. That preserves the visual source if OCR text, page handling, or later processing needs to be checked.
When should I convert the PDF to Word instead?
Use an editable conversion when the main goal is rewriting or restructuring content. Use a text layer when preserving the scanned appearance and enabling search are more important.